How we built it / Field notes 01Seattle, WA · An ongoing project
Five humans. Eleven agents. One record.
A question about which pressing to buy became an app for collectors, on the web and
in both app stores. It also became a place to learn how people and AI can build,
run, and grow something together.
Jason · Founder & product leadSeptember 7, 2026
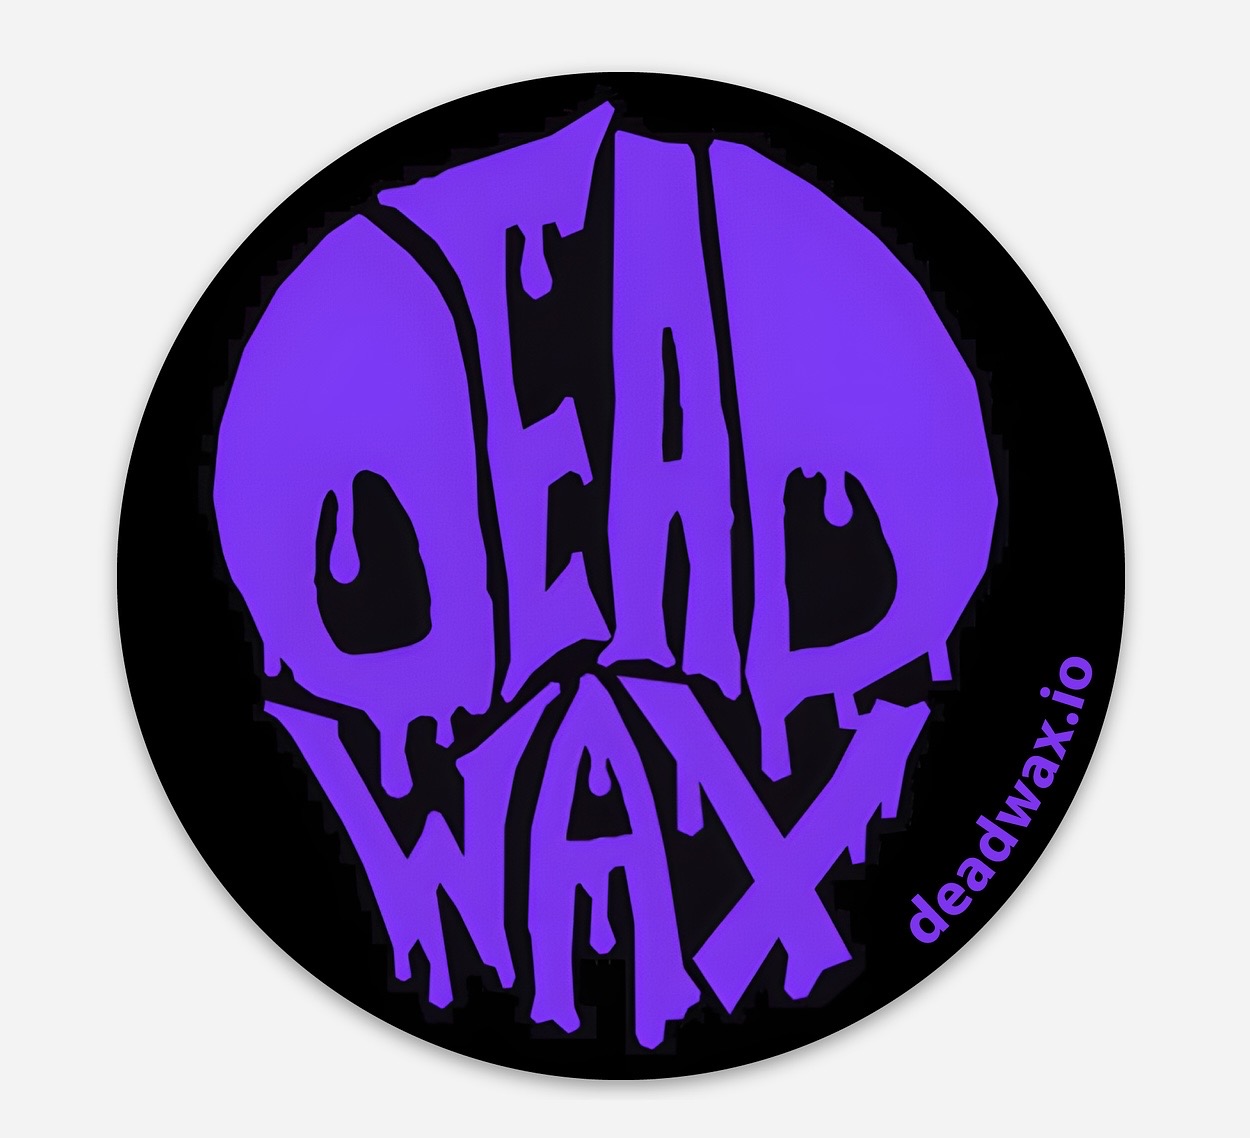
Hope drew the skull. We built a project around the things we love.
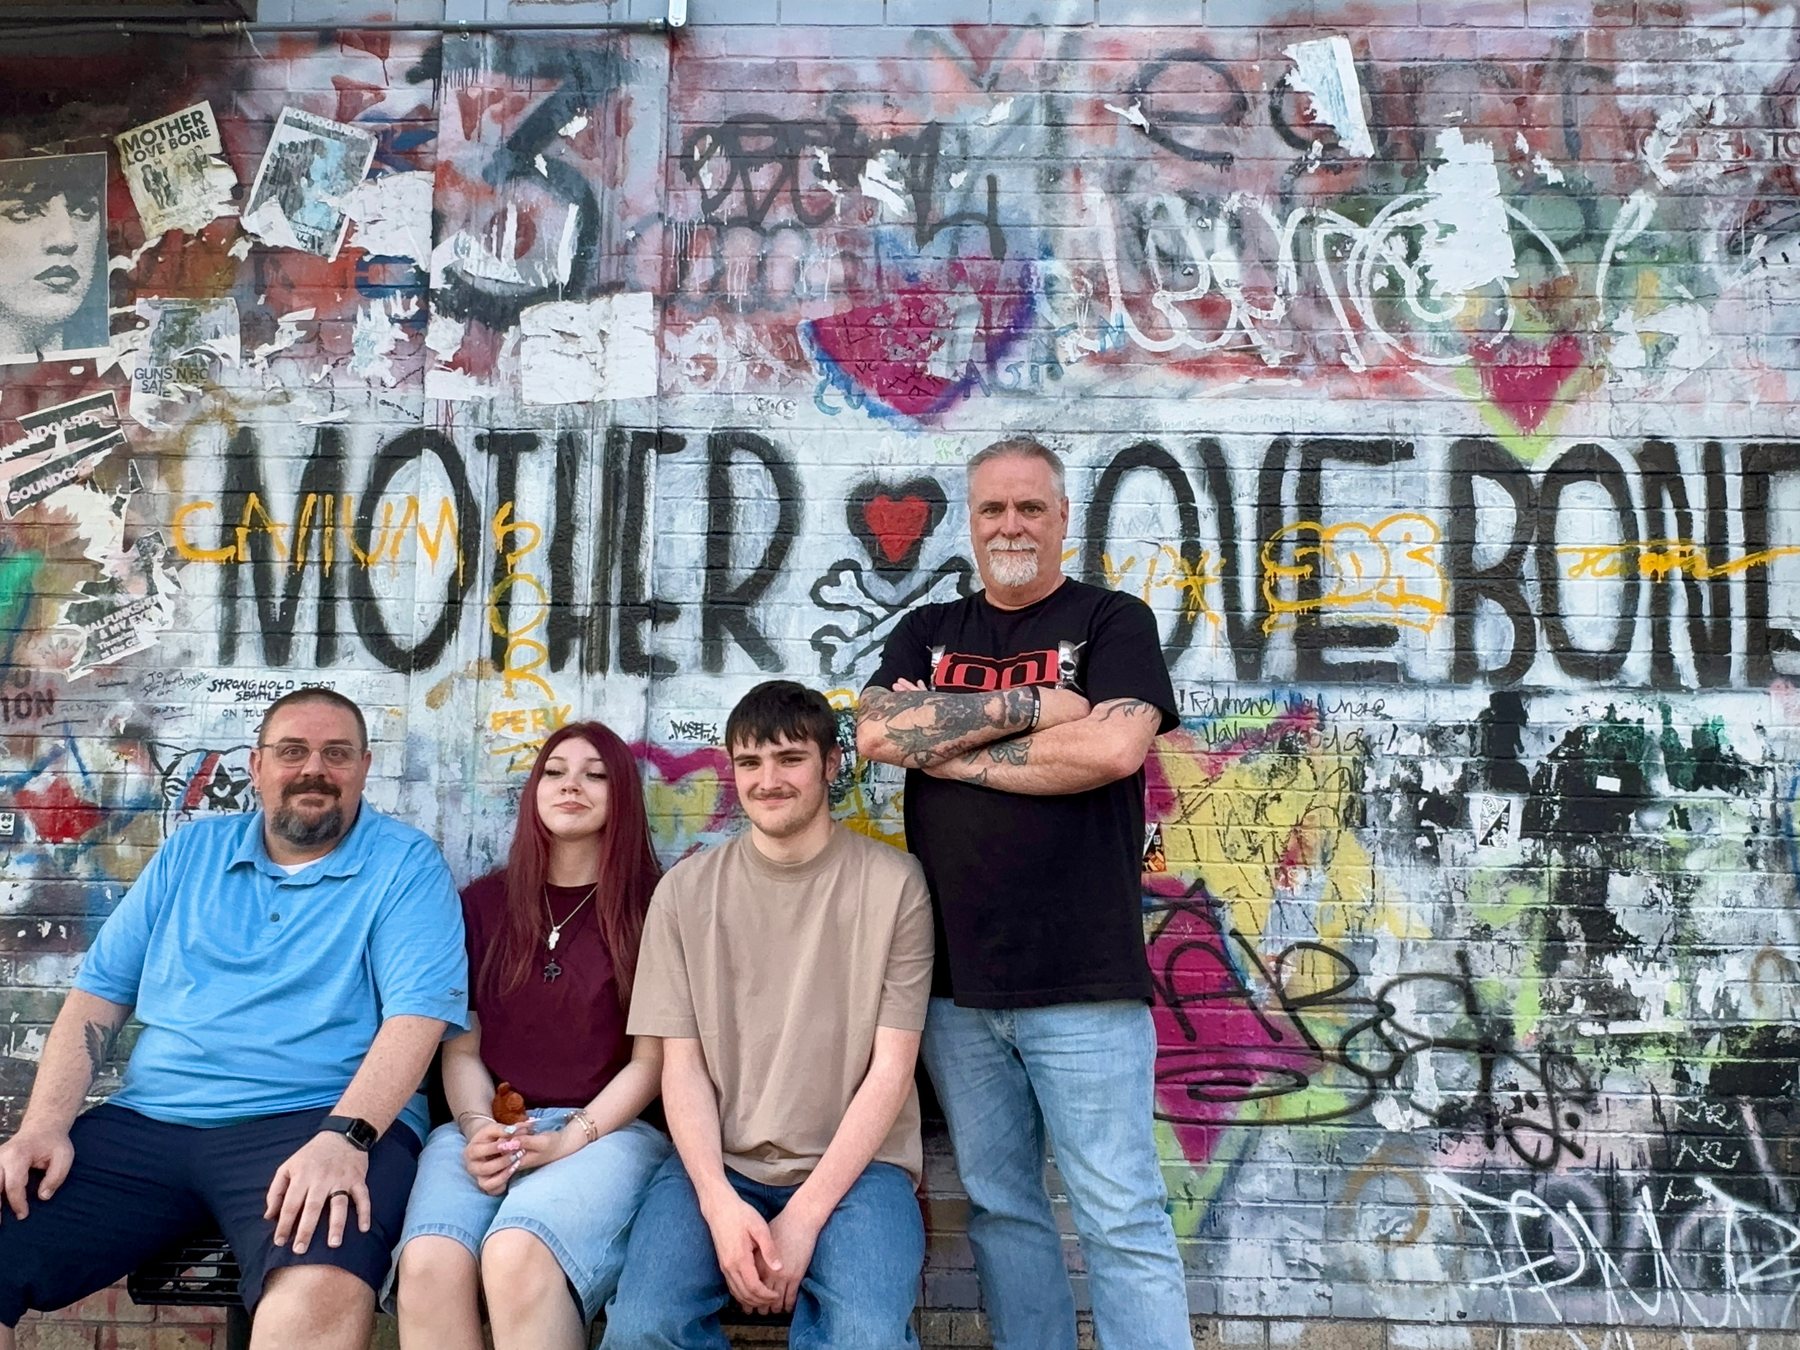
5HumansTaste, domain expertise, and every decision that matters.
11Agent rolesDefined scope, named owner, reviewable output.
3SurfacesWeb, iOS and Android, on one shared API.
6,800+Pressing panelsPanels that gave a collector usable pressing information, since May.
Records. Software. Everything we learned in between.Start the story ↓
We wanted to find the right pressing.
Two copies of the same album can look almost identical and sound very different. The
clues are there: the label, the mastering credit, the tiny letters scratched into
the deadwax. Finding them takes work.
Discogs gives collectors an extraordinary database. The research around it is
scattered across release pages, forum threads, and shootout videos. We wanted to
bring that context together, alongside the records we already own and the ones we’re
looking for.
That is the product. For me, there is a second reason to keep building it. Deadwax
is where I test the engineering practices behind AI-assisted work: how to give an
agent useful context, how to review its decisions, and how to know whether a change
made the product better. Someone is standing in a record store, holding a copy of an
album, waiting for an answer. That is a better test than a demo.
My daughter Hope drew our skull. Seeing that drawing become the app’s identity,
and then a sticker we can hand to someone, is one of my favorite parts of the
project. The code matters. So does making something with your family and friends.
We wrote down what kind of company we wanted to be, and those words go into the
agents’ working context too. “Customers first” means checking whether a feature
helps someone in a record store. “Data integrity” means saying what we know and
where the evidence runs out. “Ship to learn” means listening when a collector
tells us a feature made things worse. The principles become useful when they
change a decision.
Hope’s artwork became our visual identity.
One of our sticker designs. Something to take beyond the screen.
The humansFive · judgment
JasonFounder & product lead
Product direction, priorities, the agent workflow, and the decisions about what
we release.
ChrisPressing expertise
Collector judgment. The person who can challenge a recommendation that sounds
convincing but misses the record.
HopeVisual identity
The brand, including the original hand-drawn skull mark. Brand changes come back
to her.
CadenCommunity
Instagram, community voice, and helping the product find the collectors it is
for.
DavidAI workflow advisor
Advice on agent workflows, context, and getting more useful work from the tools.
Humans own judgment. AI owns execution within the task we give it. That is the
principle we work toward, with tests, reviews, and named human decisions around the
output.
The work ends up in someone’s record bag.
Collection and wantlist browsing. Pressing research with sources. Scanning. Stories
that give you another reason to put a record on.
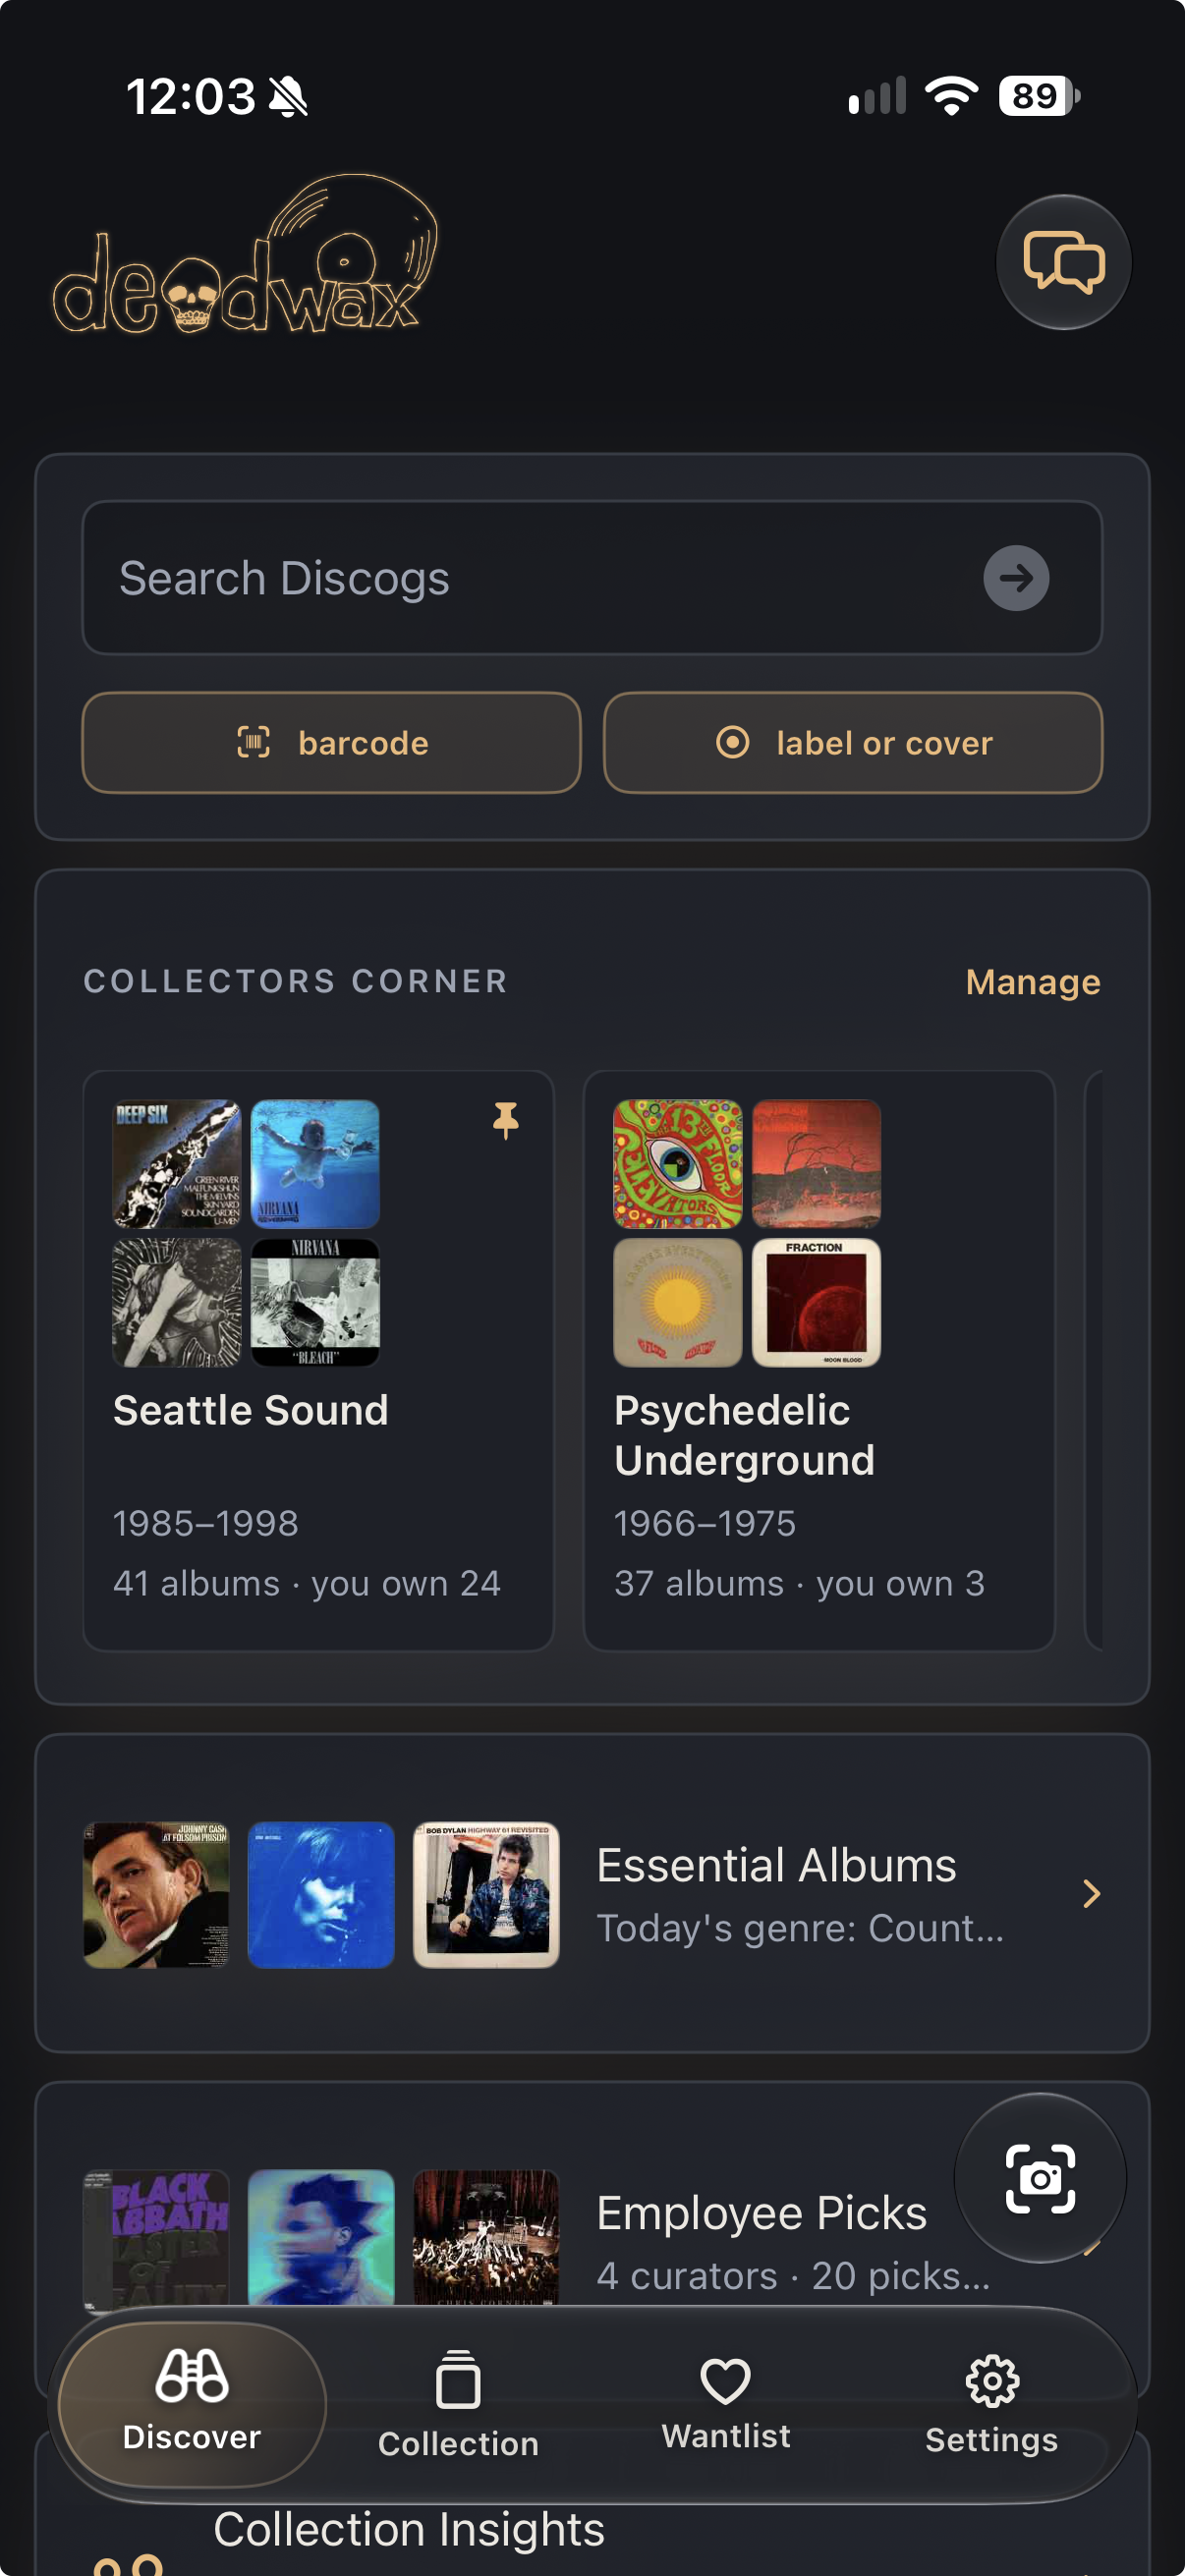
01 / Follow a sceneCollectors Corner connects records through places, labels, and musical
movements.
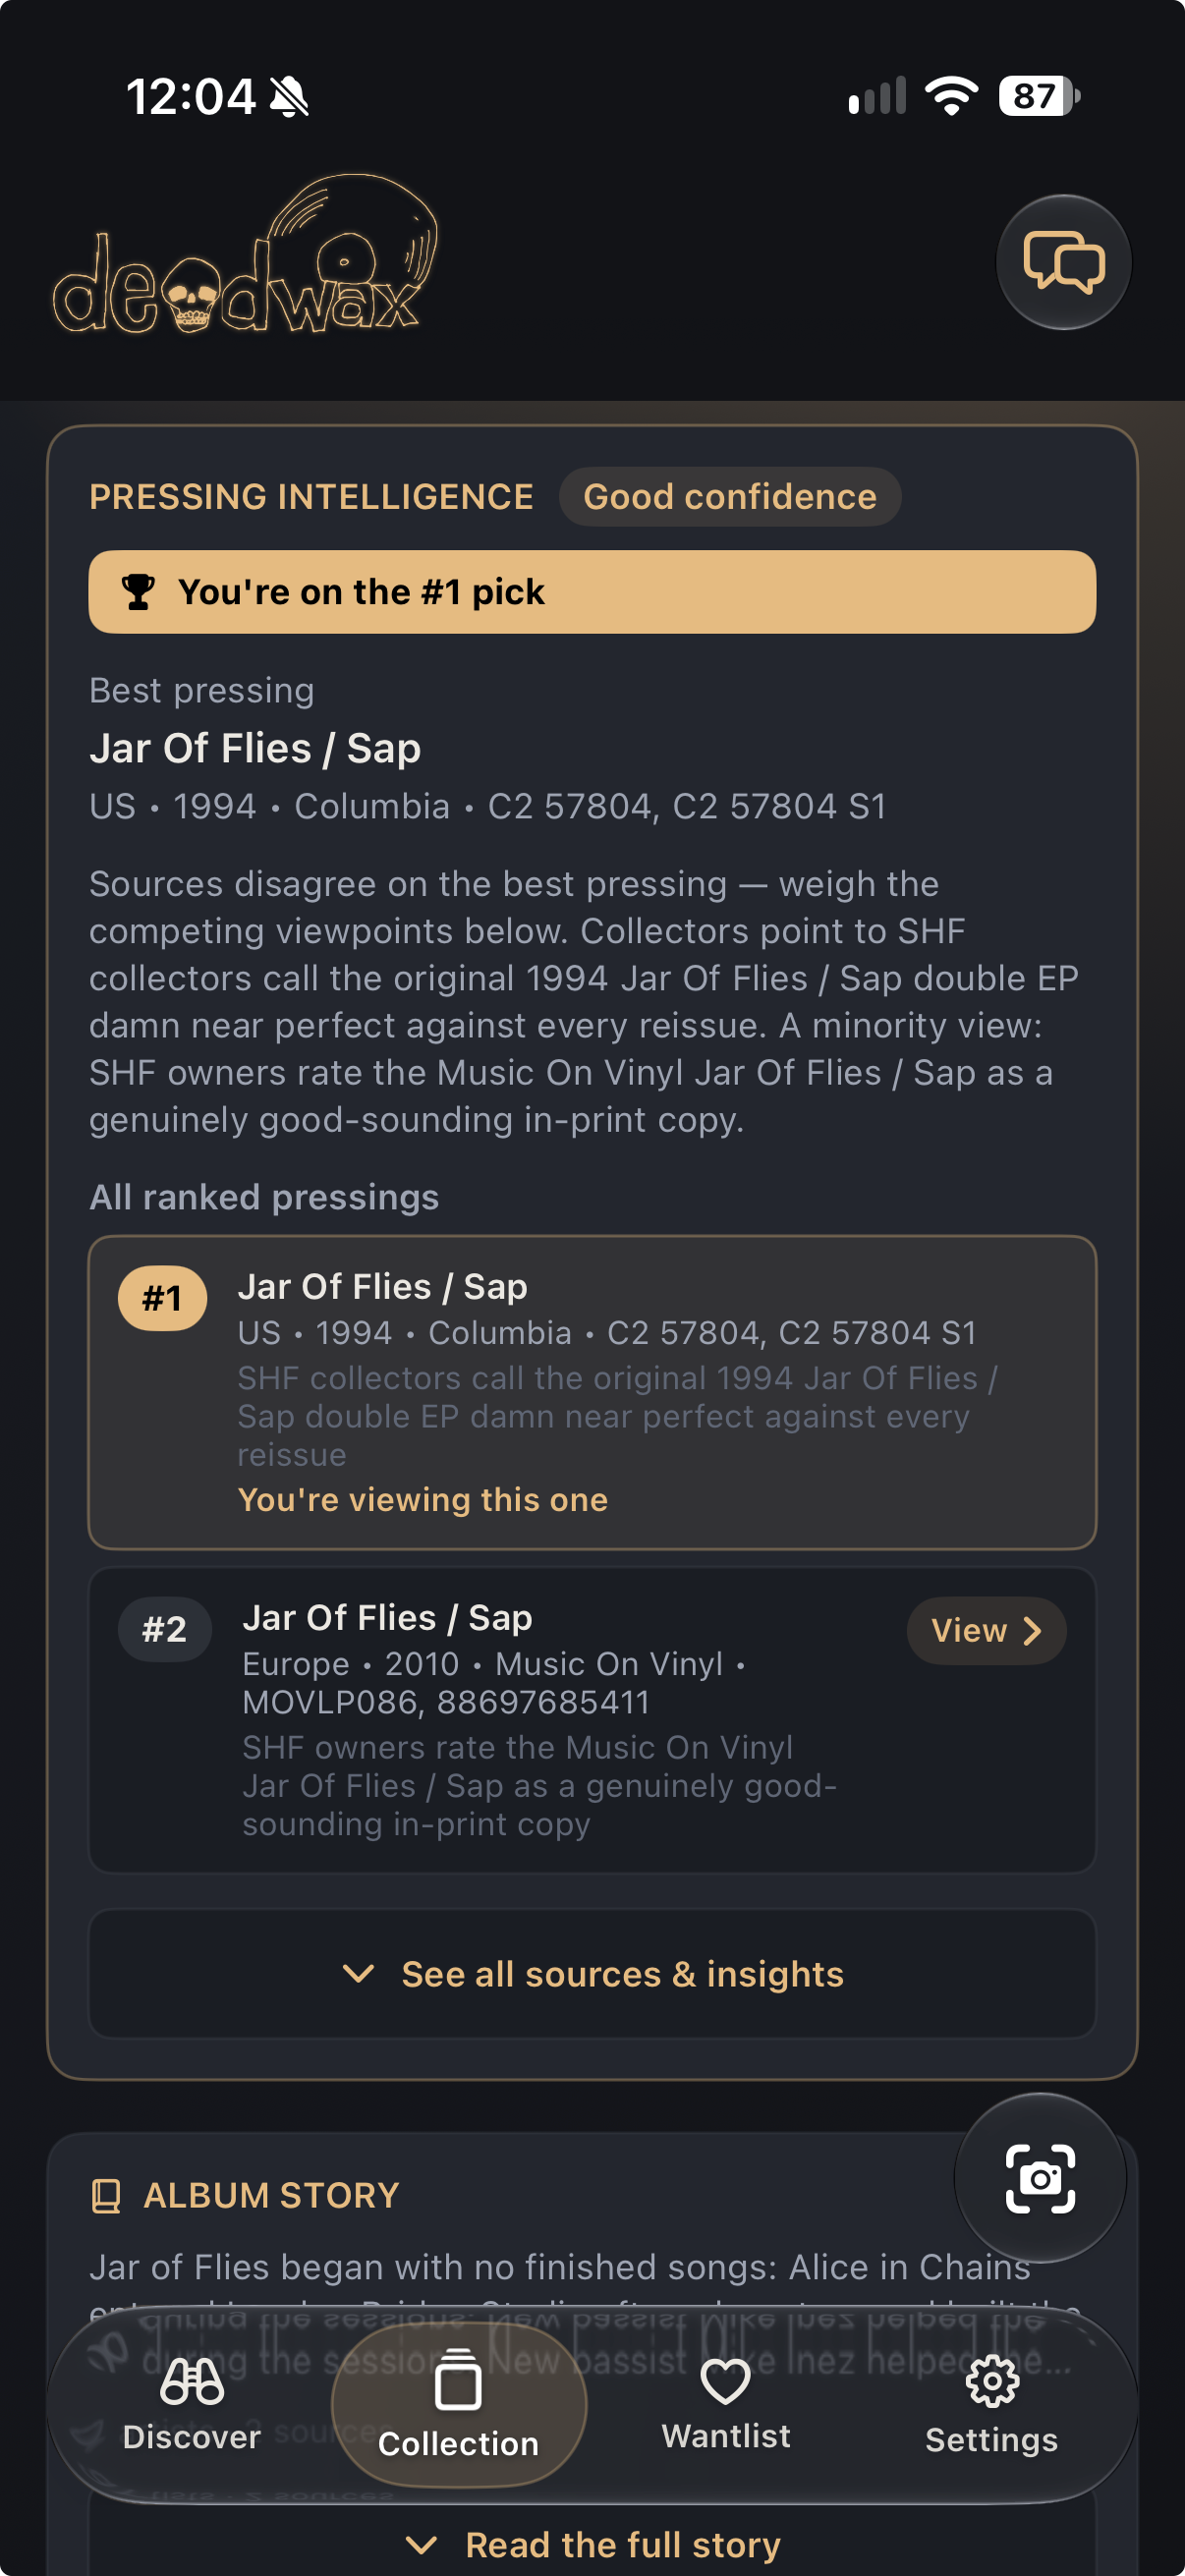
02 / Understand the copyPressing Intelligence presents recommendations, uncertainty, and the sources
behind them.
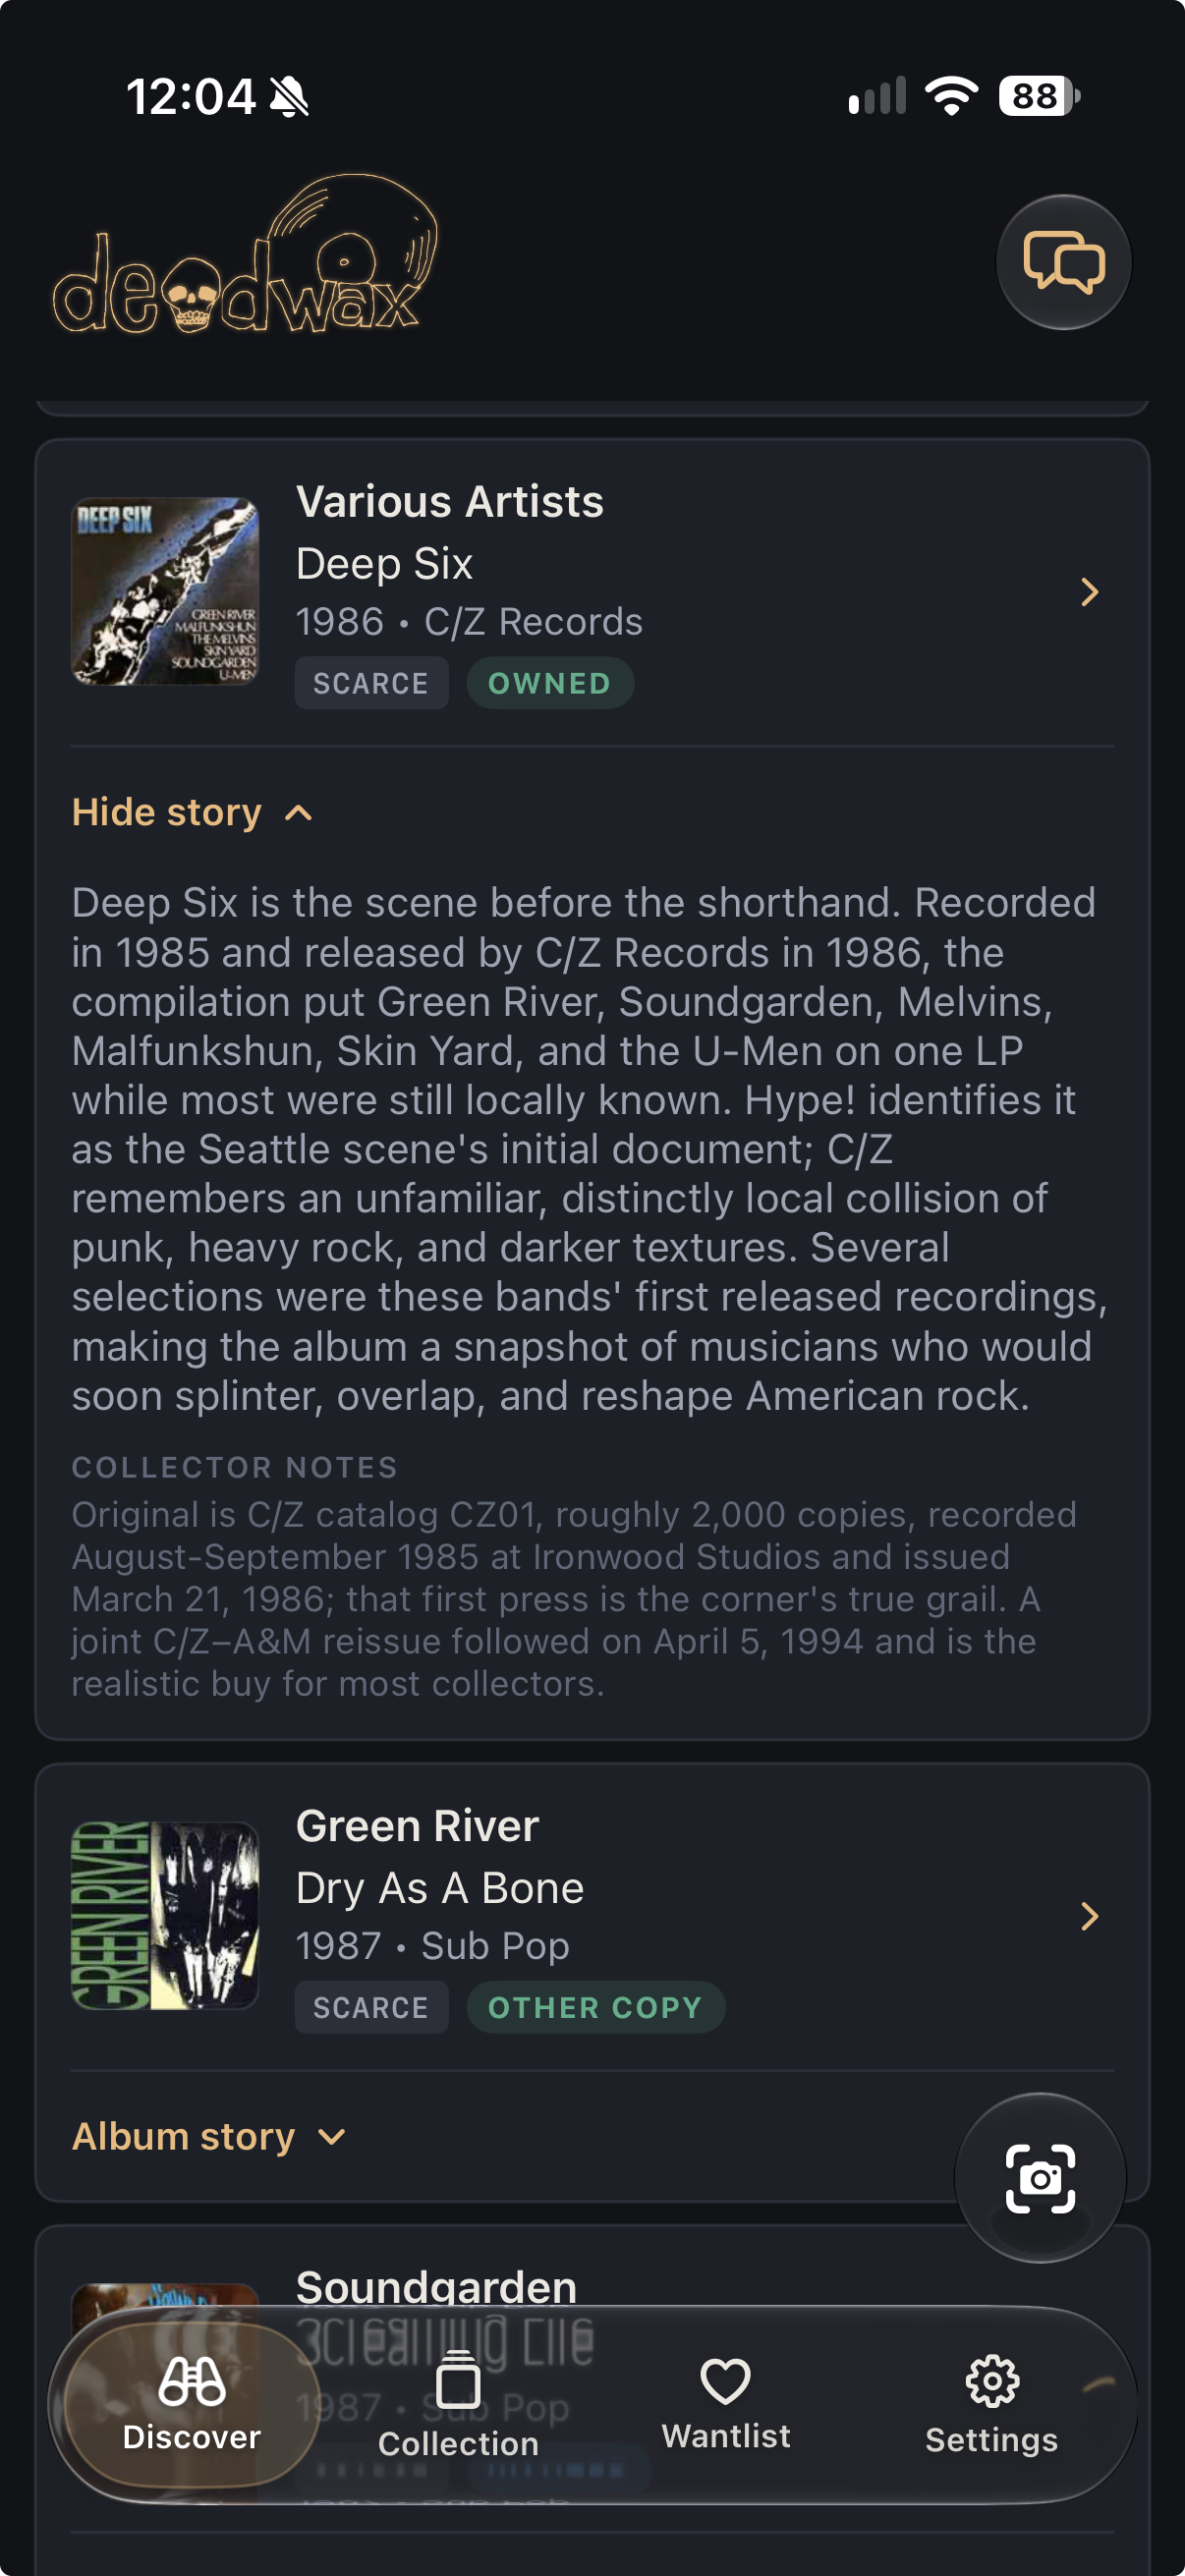
03 / Stay for the storyAlbum Stories adds the people, sessions, and accidents behind the music.
Actual iOS screens from September release work. Collectors Corner is live on web; the
latest native update is in release preparation.
Take a picture. Then read the tiny letters.
The barcode is easy. Older records often ask more of you.
We built ways to scan a barcode, read a label, and recognize an album cover. On iOS,
you can also speak the faint deadwax markings into the microphone instead of typing
them while holding the record. The app gives you a chance to check the text before
searching.
That last idea came from my own record-store habit: turn the record toward the light
and read the etching aloud. When Chris was surprised by the microphone turning on
after a scan, we changed the flow to ask before enabling it. A small conversation
became a product rule.
The camera can help identify the album. The label and the runout can help
distinguish the pressing. Keeping those steps connected, without pretending the
sleeve proves the exact copy, is the interesting design problem.
01
The sleeve
Recognize the album from its cover.
02
The label
Read the label and catalog details.
03
The deadwax
Speak the markings, check the text, find the pressing.
These are distinct recognition paths. The current cover-recognition implementation is
on iOS; native barcode and label workflows also serve Android.
Shipping the app changed the experiment.
The first challenge was getting something useful into people’s hands. The next was
learning how to keep it useful.
We began with a fairly elaborate cast of agent roles: product, design, engineering,
architecture, testing, marketing, and legal research. It helped us divide unfamiliar
work. But the org chart was never the result. After launch, we spent more time
simplifying the operating model and following the problems collectors actually
reported.
The web app gives us a starting point.
Deadwax goes live on the web. The core idea is narrow: connect an existing
Discogs account, browse vinyl, and make pressing research easier.
The web app becomes a foundation for iOS.
We choose to build a native iOS app against the same backend, carrying the
collection and pressing-research work into a new interface.
iOS reaches the App Store.
The May 7 launch adds a new kind of work: store releases, device behavior, large
collections, and feedback from people outside the project.
We change how we run the work.
The daily launch routine stops fitting a live product. We separate ongoing fixes
from larger feature projects. Claude becomes the primary developer and
orchestrator; Codex becomes a focused review and specialist layer.
Android v1 goes public. We also undo a feature.
Deadwax reaches Google Play. On iOS, we roll back batch scanning after
collectors tell us the camera flow hides the pressing results they came to see.
A feature can function correctly and still be the wrong experience.
More reasons to explore. Better questions about AI.
Collectors Corner grows to 18 curated scenes, with Album Stories and pressing
context. The next engineering priority is an evaluation lab: compare models and
workflows on the same real tasks, then decide what earns its cost.
I started by giving the agents jobs. Then I had to teach them what good work looked
like here.
Eleven roles came out of that. Not eleven employees — eleven jobs with a defined
scope, a named owner, and output somebody has to be able to review. People still
decide what to publish, what to spend, and which legal or product questions need
more help.
At first, much of this meant separate Claude and Codex sessions with instructions I
carried between them. We moved more coordination into shared files and reusable
workflows as the project grew. Today, Claude does much of the product development,
Codex supplies independent review and selected specialist work, and Gemini helps
extract pressing evidence from videos. The scheduled jobs have their own
configuration. The team has changed shape more than once.
The role is only the starting point. Each agent needs the mission, the relevant
product decisions, the design rules, the code it will touch, and the test that will
tell us whether it has finished. That is context engineering. The surrounding tools,
permissions, scripts, checks, and handoffs are the harness. Building that working
environment has become a large part of the project.
I have used models such as Fable, Astra, Sonnet, and Sol for different kinds of
work. We give subagents bounded tasks and route simpler work to faster, less
expensive models, with stronger models for difficult reasoning and review. Shared
context keeps each handoff from becoming another round of rediscovery. We record
those choices in CLAUDE.md and AGENTS.md, then revisit
them when the results or the cost stop making sense.
The agent rolesEleven · execution
Director / OrchestratorClaude
Task packets, dependencies, merge order, and the handoffs between the rest.
Product ManagerClaude
Scope, priorities, user stories, acceptance criteria and the metrics we judge
them by.
Designer & ResearcherClaude
Collector workflows, visual rules, accessibility, and using a phone with a
record in your other hand.
ArchitectCodex
Independent review. Reads the diff before a merge and blocks on real findings.
Backend DeveloperClaude
Authentication, API behavior, data pipelines and reliability.
Frontend DeveloperClaude
The web app, responsive workflows and interaction details.
Tester / QAClaude
Regression tests, browser automation, CI and the evidence behind a release.
Swift iOS DeveloperCodex
SwiftUI, Apple conventions and how the app behaves on an actual iPhone.
Android DeveloperCodex
Kotlin, Compose, Material 3, and native Android behavior.
Marketing ManagerClaude
Positioning, go-to-market, community and launch material. A person still decides
what we say.
Legal & Compliance AdvisorClaude
Research on naming, privacy, licensing and API-use questions. Advisory, never
the final word.
These are reusable responsibilities, not eleven continuously running employees. Claude
does most of the product development and orchestration; Codex supplies the independent
review and the two native specialties. Gemini’s video extraction and the claim judge
are product-data and evaluation jobs, outside this roster.
Every change walks this line
Can stop the line
01
Worktree
The agent gets its own copy of the repository, cut fresh from main — the code
and the written strategy it works from.
02
Local checks
The regression bundle runs on this machine first. CI minutes and deploys are
money.
03Gate
Independent review
A second model reads the diff and blocks on real findings. Expect several
rounds.
04
Pull request
Rebased onto main. Protected files are stripped before anything is pushed.
05Gate
CI
Security rules, lint, types, unit tests, browser tests, and the native builds.
06
Merge
Squash onto main, delete the branch. The agent never merges its own work
unreviewed.
07
Deploy & verify
Backend, then the site and CDN. Then we exercise the changed route in
production.
08Human
The human gate
A store release waits for a person. Chris and I use the build with a record in
hand.
Some of these are machinery. Some are discipline. A script resets
our strategy documents out of a change before it can become a pull request, and a
check fails the pull request if they survived. Another refuses to tell a collector
their bug is fixed until a person has confirmed it. The rest — merging only on
green, waiting for a human before a store release — are habits we hold ourselves to.
Knowing which is which is the part that matters.
Write the script first.
When work has a repeatable answer, we write a script. We add tests for the script,
run them whenever it changes, and have the agent use that tested script. Review
preparation, test runs, branch cleanup, deployment, and pressing-data validation all
follow this pattern. It saves the agent from rebuilding the same sequence of
commands and gives us something we can inspect and improve.
That rule lives in CLAUDE.md and AGENTS.md: deterministic
work belongs in scripts. Skills guide the parts that need judgment. Before an agent
starts improvising, it should check whether we already have a tool for the job.
Make the checks inspectable.
Our everyday evaluation of code quality starts with tests. Unit tests check the
logic. Playwright walks through browser workflows. GitHub Actions runs those checks
alongside lint, type checks, and builds. Each produces a result we can inspect: what
passed, what failed, and where. Coverage reports help us see what we have not
tested. An agent saying the work is finished is not enough.
We automate native experiences in simulators and emulators, too. On Android,
wireless debugging lets us install a build and exercise it on a real phone. These
checks bring us closer to the experience a collector will actually have, including
the camera, touch targets, and navigation.
Browser tests can also be flaky. We keep their attempt history, look for the same
test failing and passing without a code change, and use a managed quarantine process
with an owner and a repair deadline. A retry is evidence about instability. It is
not permission to forget the first failure.
We use a language model as a judge when the question needs interpretation, such as
whether a pressing claim is supported by its source. It works from a rubric and
known bad examples. That is another kind of evaluation, alongside the deterministic
tests that check our code. Neither can tell us, on its own, whether the product is
ready for someone else to use.
The useful question is how much of the work we can trust, and what evidence would
change our minds.
A working principle, still being tested
Field note / Reliability
The server said success. The collection stayed out of date.
A large collection exceeded the response limit between our backend and the client.
The handler finished, but the app still failed to receive the collection. We changed
the delivery path and verified the complete request. That incident sharpened a rule
we now use throughout the project: check the result where the user experiences it.
Field note / Feedback
“Deployed” was too early to call a bug fixed.
Our feedback tracker used issue closure to tell a reporter their problem was fixed.
A merged pull request or a successful deployment could trigger that message before
anyone had reproduced the result. We now keep a fix pending until someone confirms
the behavior on the released build. Automation can move the work along; it still
needs a truthful finish line.
Field note / Evaluation
A convincing answer needs something to answer to.
Pressing Intelligence can attach a real comment to the wrong edition, overstate a
reviewer’s opinion, or rank a weak match too highly. We already keep reference cases
and evaluate ranking and claim support. Some checks report results for review rather
than blocking a release. The broader AI Evaluation Lab is the next experiment: test
the models, prompts, and handoffs themselves.
We use established tools so the experiment can focus on how we work. Each native app
has its own interface; the product rules and data meet in the shared API.
A collector reports a bug. Another opens an album we have not researched well
enough. Both can become the next piece of work, without waiting for me to sit down
at the desk.
A bug report can reach production before I read it.
It still cannot be called fixed until a person has seen it working. We learned
that one the embarrassing way.
T+0
Someone tells us
A note from the app becomes a tracked issue.
On the hour
Triage
Priority, effort, and whether it is safe to fix without a person.
Same run
The fix
A scoped change on its own branch, with the tests that prove it.
Here the machine runs out of authority. The reporter sees “Fix Pending”.
Only a person
Fixed
Somebody sees the symptom gone on the build the reporter is running.
What it will not touch
Sign-in and sessions, anything holding a token, data schemas, infrastructure and
the workflows that enforce these rules. Those paths are protected by the same
checks that block a human in a hurry. Ambiguous asks and anything that looks like
a redesign stop and wait for a decision.
What happens on a quiet hour
Nothing. The job reads the queue, finds no real event, and exits. Most hours are
quiet hours, and a loop that invents work to justify itself is worse than one that
goes back to sleep.
Half an hour later, a second job looks at the albums collectors actually opened and
finds the gaps in our pressing research. Demand tells us where the work would be
useful; our evidence rules decide whether it belongs in the product. Sometimes the
right outcome is to leave a record with facts only, or change nothing.
The loops are deliberately not the same shape. A code fix, an additive data update,
a model extraction, and an analytics refresh each need different checks. They have
locks, failure reporting, and a way to stop them. They are scheduled software with
an agent inside, and they need maintenance like the rest of the product.
Every hour · :00
Listen to collectors.
Feedback triage and permitted fixes.
Every hour · :30
Follow the records.
Research gaps from recent album opens.
Scheduled batches
Keep the evidence useful.
Video extraction, reporting and cost history.
The hourly jobs are installed local scheduled tasks. Cloud schedules are defined in
GitHub Actions. The paper documents the current configuration, limits, and differing
release paths.
Cumulative views of panels that deliver usable pressing information to a collector.
We count the moment a collector receives usable pressing information. That is close
to the reason the product exists: helping someone work out which version to own,
buy, or keep. Generic page traffic does not tell us whether we delivered that value.
We work on both sides of that moment. Search and scanning help collectors find the
record. Collection and wantlist browsing put their own music in reach. Stories and
Collectors Corner give them reasons to explore. The PI research loop improves the
evidence for the albums they open.
A growing counter needs questions around it. Are different collectors reaching PI,
or only the same few? Is useful information available when they ask? Do their
collections load? Does the panel take too long?
40%PI activation
80%PI availability
95%Collection load success
< 2sPI P90 load time
These are our guardrail targets, not a claim about today’s results. P90 means nine out
of ten measured loads finish within that time. Definitions, sample sizes, and coverage
matter.
The Admin dashboard gives me the detail behind those questions: daily, weekly, and
monthly use; return visits; platform and version adoption; collection failures;
search and scan outcomes; source clicks; wantlist and collection actions; and
feedback. It also shows how people explore corners, open stories, choose themes,
sort, filter, and roll the dice for a record.
Reliability and economics are part of the same view. We track errors, latency,
rate-limit pressure, modeled usage costs, and actual AWS cost history. Estimates and
bills have different labels. Missing history stays visible. I want to understand why
the number moved before deciding what to build next.
Deadwax has given me a reason to learn the work around the software, too.
That has included preparing store releases, making launch material, testing ads on
Meta platforms, and figuring out how to introduce the product to collectors without
talking like a software pitch.
Agents help me research options, draft material, and compare approaches. I still
have to choose what to say, check the claims, decide what to spend, and put my name
behind the result.
Ads are their own product problem.
We ran a small Facebook and Instagram advertising test in August. Ad review also
changed the creative: a paid ad needed a different treatment from an organic
product demo. For the Android launch, the plan separates store destinations and
creative by platform so the results will be easier to interpret.
Meet collectors where they are.
Our September Google Play announcement went to the Steve Hoffman Music Forums. It
thanked beta testers, showed the collector workflow, and invited corrections.
Caden brings the same attention to our Instagram presence. The app has to earn
interest through something people can use.
Measure more than a click.
The marketing question is whether someone reaches the store, tries the app, and
finds enough value to return. We are still learning how to measure that journey.
We do not have a validated acquisition-cost or advertising-return story to tell
yet.
This is what makes Deadwax a useful lab for me: product decisions, engineering
choices, costs, trust, and distribution all affect one another. I get to see where my
assumptions meet the real world.
A roadmap with some miles on it.
Android is out of beta. Core search, scanning, and the prioritized Pressing
Intelligence expansion have shipped. The next work goes deeper on quality, feedback,
and the value of the collection itself.
In collectors’ hands
Available
Web, iOS & Android v1
The app is public on the web, the App Store, and Google Play. Collection and
wantlist browsing share the same backend.
Search, scans & pressing research
Forgiving search, native barcode and label/deadwax workflows, and
source-backed pressing context. Coverage continues to vary by album.
Read the label. Speak the runout.
Native label capture and spoken deadwax make faint markings searchable. iOS
cover recognition adds an album-first entry point.
Use the collection you have
Sorting, filters, current record values, and dice or shake-to-roll help
collectors spend time with their own music.
The PI evaluation foundation
Reference cases, output-ranking checks, and a separate claim-support judge.
Weekly output evaluations currently report for review.
Working on / up next
Current priorities
AI Evaluation LabFirst priority · baseline phase
Establish baselines, then compare models, reasoning effort, prompts, and
workflows on fixed tasks. Measure correctness, cost, time, and review burden.
Stories & Collectors CornerFinish native distribution
Album Stories and 18 curated corners connect records to their scenes. Already
live on web, the latest native updates are built and tested. The iOS build is
uploaded to App Store Connect; Android is signed and device-tested. The next
step is completing human release checks and public store distribution.
Ask for feedback at useful momentsNext product priority · planned
Invite feedback after meaningful collector workflows, with careful triggers
and limits so the app does not become an interruption.
Further out
Planned / research
Collection value & insights
Build on current record values with better collection insight. Historical and
market-source work depends on the data we can responsibly use.
Better handoffs between agents
Evaluate what survives a change of model or working environment: decisions,
constraints, unfinished work, and the evidence behind them.
Stereo equipment planning
Explore useful gear context and AI-assisted discussion. Privacy, sources,
cost, and scope need decisions before this becomes a product promise.
These are priorities, not release dates. We update the order as we learn. The
technical paper separates the evaluation tools that exist today from the lab we are
planning.
The details are part of the story.
The companion paper follows a request through the system, explains how pressing
evidence becomes a recommendation, and documents the safeguards, failures, and
evaluation work behind the product.